Enterprise AI Agent Platform
Grounded Q&A system using LangGraph cyclical multi-step orchestration, ChromaDB vector indexing, and FastAPI asynchronous streaming.
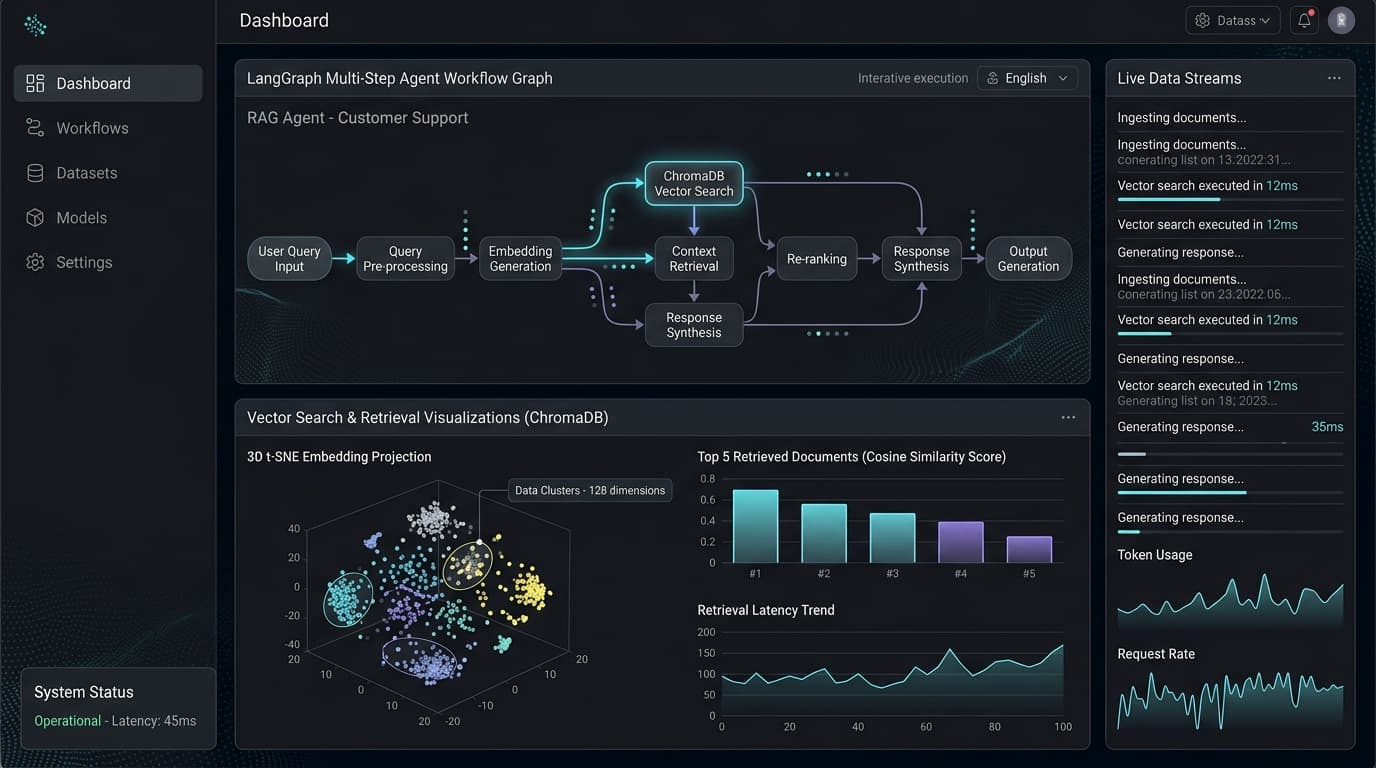
Key Architecture & Highlights
Engineered for extreme reliability, low latency, and deterministic execution under real-world operating constraints.
Cyclical Agentic State Machine with LangGraph
Constructed a multi-step graph featuring query rewriting, document grading, fallback web search retrieval, and answer hallucination checks before streaming the final response back to the client.
ChromaDB High-Density Vector Search
Chunked heterogeneous enterprise PDFs, Markdown files, and internal policies using recursive character splitting with semantic overlap, generating normalized vector embeddings with sub-60ms retrieval benchmarks.
Asynchronous High-Throughput FastAPI Engine
Architected ASGI endpoints utilizing Server-Sent Events (SSE) to deliver real-time token streaming, comprehensive token usage monitoring, and sub-100ms response start times.
Factual Grounding & Footnote Attribution
Enforced strict system prompt guardrails that compel the synthesis engine to cite exact document chunks and page numbers, returning structured confidence intervals for every claim.
Technologies & Infrastructure
System Design & Engineering Decisions
Enterprise knowledge bases often suffer from document fragmentation, hallucinated LLM responses, and high retrieval latencies across large corpora. The Enterprise AI Agent Platform was architected to eliminate ungrounded statements through an explicit cyclical state machine built with LangGraph. Instead of naive single-shot vector lookups, the platform breaks incoming complex user inquiries into semantic sub-questions, executes parallel vector embedding lookups across ChromaDB collections, grades retrieved context for relevance, and only synthesizes final answers when confidence thresholds are rigorously satisfied.
Verified Highlights & Protocol Constraints
- Built an AI-powered question-answering system using Retrieval-Augmented Generation (RAG) and LangGraph to orchestrate document retrieval and LLM-based response generation.
- Implemented semantic document retrieval using vector embeddings and ChromaDB to retrieve relevant context for user queries.
- Developed a Python and FastAPI backend exposing AI workflows through secure REST APIs and real-time streaming endpoints.
- Integrated LLM APIs to generate context-aware responses strictly grounded in retrieved document content with citation footnotes.
Gallery & Live Screenshots